Developer productivity metrics show how well a software team turns engineering time into reliable, useful changes in production. No single number can do that job, so a working set combines several views: delivery speed, stability, code quality, the flow of work, where engineering hours go, how developers experience their work, and what users get in the end.
Executives often want a quick answer and reach for numbers that look reliable from the outside, such as lines of code or hours online, but say little about the actual work of developers and erode their motivation. This guide covers 20 metrics that hold up better, with a formula and a counter-metric for each, the frameworks they come from, the benchmarks worth comparing against, and a starting scorecard for a small team.
- What software development metrics measure
- Why developer performance is hard to measure
- Developer performance metrics that don’t work
- Frameworks behind modern engineering metrics
- The best developer productivity metrics
- DORA benchmarks: what good delivery looks like
- Performance metrics for individual developers
- All metrics at a glance
- Which metrics to start with
- How to combine metrics into a scorecard
- Metrics for teams using AI coding tools
- How actiTIME supports time-based developer metrics
- FAQ
What software development metrics measure
Software development metrics describe a team’s work at three levels, and a metric that is fair at one level can be meaningless at another. As McKinsey’s own example shows, deployment frequency is a sound way to judge a system or a team, yet it depends on everyone doing their part, so it tells you nothing about a single developer.
| Level | Questions it answers | Example metrics |
|---|---|---|
| Organization or system | Do we ship reliably? Where does the engineering budget go? | DORA metrics, investment balance, cost per feature |
| Team | Where does work get stuck? Can we plan a sprint and keep to it? | Cycle time, work in progress, planning accuracy, developer experience score |
| Individual | Is this person meeting the expectations of their role and growing? | Evidence tied to the role, peer feedback, quality of their own changes (see the section on individuals below) |
A second lens is how far along the chain from effort to value a metric sits. Kent Beck and Gergely Orosz describe software work as a sequence of effort, output, outcome, and impact, and point out that the earlier in that sequence you measure, the easier the metric is to collect and to game.
| Stage | What it captures | Example metrics | Risk of gaming |
|---|---|---|---|
| Effort | Time and activity put into the work | Hours logged, commits, meetings attended | Very high |
| Output | Things the team produces | Pull requests merged, story points, features shipped | High |
| Outcome | Changes in how the software or its users behave | Change lead time, change fail rate, feature adoption | Moderate |
| Impact | Value that returns to the business | Revenue from a feature, retention, support costs | Low, but hard to attribute to anyone in particular |
A metric turns into one of your engineering KPIs once it gets an owner, a baseline, a target, and a deadline. A team usually carries only a handful at a time, the same way project KPIs work in other parts of a business. A few examples of software development KPIs written that way:
- Cut change fail rate from 14% to 8% by the end of the second quarter (owner: platform lead)
- Bring the median time to first code review under one business day within two sprints (owner: team lead)
- Keep unplanned work below 20% of team hours for the quarter (owner: engineering manager)
Why developer performance is hard to measure
Neither what a developer puts in nor what comes out can be captured in one number, and people differ so much that individual results swamp everything else.
Let’s start with the definition of productivity, which equals output divided by input.
Productivity = Output / Input
This formula looks simple, but many issues related to measuring developer productivity can be resolved by referring back to this definition, in particular, to what we mean by input and output in the work of a developer. If any of these components are defined incorrectly, then productivity won’t be measured objectively.
What is developer output?
What should be considered as the output of the developer’s work? Is it lines of code because it’s exactly what developers produce? Is it function points? Or is it bugs fixed? In practice, these metrics have little to no relevance to the economics of the business and don’t reflect any degree of developer effort by themselves.
If we remove the business economics from the definition of the output, we’ll get the definition of productivity that is isolated from business profits. Let’s say work on a project was completed successfully, but the product turned out to be a total failure on the market so it has no potential to generate any revenue. Judging from this perspective, does it matter if the project was completed on time and the work of developers was effective?
What is developer input?
Input refers to the investments made by developers, such as time and effort. Comparing time across activities makes no sense, because developer activities are more than sets of similar tasks: they involve different degrees of complexity, collaboration, and other factors that undermine the reliability of the time metric alone.
Or how do we measure the developer effort? Activity monitoring software attempted to measure how productive users are by registering mouse clicks, keyboard taps, types of apps and websites used, and time spent on them. While it is a minimal unit of the developer activity, it has nothing to do with productivity or effort.
Look further into possible inputs and outputs, and neither of them can be pinned down precisely, which makes it hard to choose reliable developer performance metrics. On top of that, the accuracy of these measurements is distorted by the 10x variation phenomenon.
What is the 10x variation phenomenon?
In 1968, Sackman, Erikson, and Grant conducted a study where they tried to measure whether people were more productive when programming online or offline. They studied professional programmers with an average of 7 years’ experience and found the following:
- Range of initial coding times: about 20:1
- Range of debugging times: over 25:1
- Range of program sizes produced: 5:1
- Range of program execution speeds: about 10:1
What they found is that they were unable to determine which group of programmers was more productive because individual productivity differences drowned out differences attributable to online and offline performance. So, differences found in coding time, debugging time, and program size all support a general claim of differences in productivity, i.e., a 10x difference. The study had flaws, such as mixing programmers who wrote in low-level and high-level languages, but Steve McConnell notes that even after correcting for them the gap stays above tenfold. This research is also where the idea of the 10x developer comes from.
A number of similar studies have been conducted since 1968. Take a look at their productivity ratios for teams and individuals.
Individual ratios in these studies range from about 2:1 (Cartwright and Sheppard, 1998) to 28:1 (Sackman and colleagues), and the team-level ratios in Barry Boehm’s 1981 and 2000 data are 4.2:1 and 5.2:1.
All these studies prove that the differences in productivity are very high on both individual and team levels, which produce the following conclusions:
- The results of these studies proved that if we measure the impact of a process, practice, or environmental factor, the measurements will be subject to the 10x individual variation factor, meaning that they are very unlikely to be valid.
- If we try to assess individual or team productivity, these measurements will be confounded by process, practice, or environmental differences between projects.
Developer performance metrics that don’t work
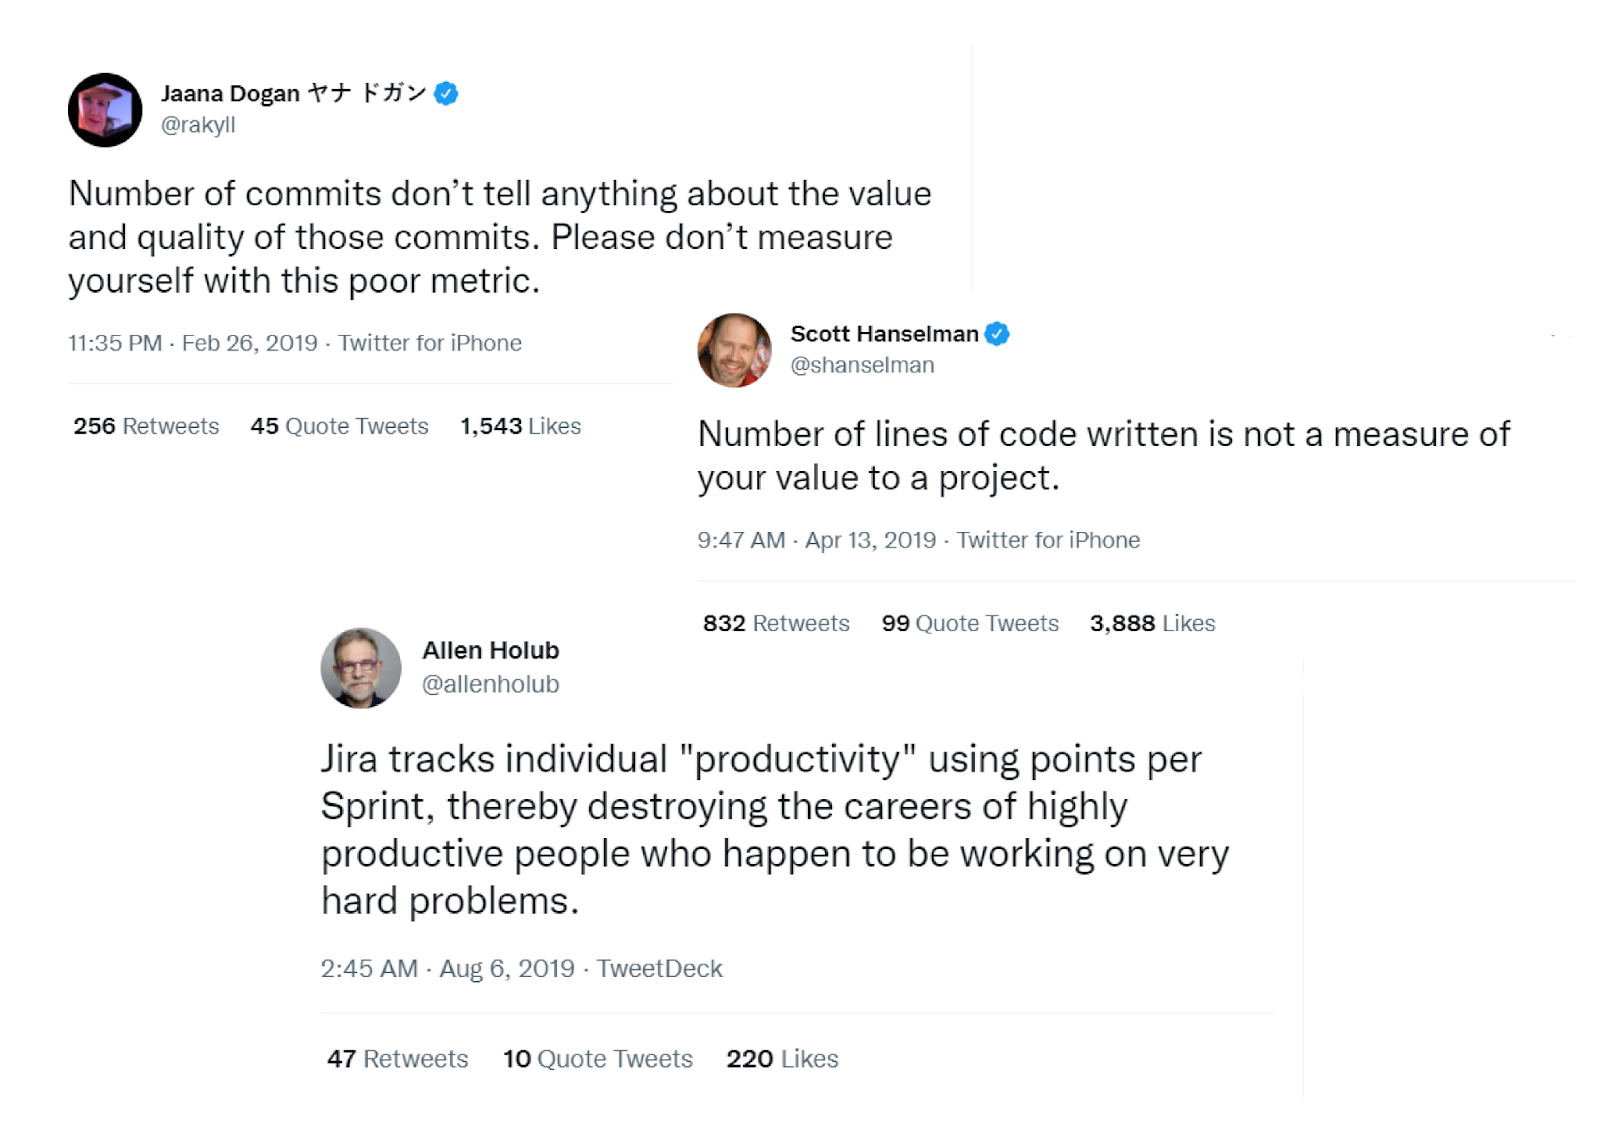
Metrics that count activity, such as hours, lines of code, or commits, tend to backfire: they are easy to inflate and say little about the value a team delivers.
Executives seek to measure performance in development teams for a number of reasons. Steve McConnell, project management and software engineering expert, provides the following most common reasons:
His list spans three levels. At the organization level, executives want to compare themselves with competitors, track progress, and decide how much work goes onshore, offshore, or to outsourcing partners. At the team level, they want to see which teams others should learn from, evaluate team managers, and split bonuses and work between teams. For individual developers, they want input for staffing decisions, performance reviews, and bonuses.
The biggest issue with measuring developer productivity is that managers introduce metrics that make little to no sense in regard to developer performance. Here are some of the most common examples of the worst developer performance metrics:
- Hours worked
- Lines of code
- Bugs fixed
- Tasks completed
- Number of commits
- Velocity points
- Pull request count
- Features shipped
- Computer activity metrics
Using these metrics is very likely to be detrimental to developer morale and business growth: none of them takes into account developer experience, business output, or what programming is truly about. Just as lines of code don’t reflect the developer’s efforts, the number of bugs fixed doesn’t mean better quality software, and low keyboard or mouse activity doesn’t mean anything at all. Instead, these metrics invite developers to game them by writing unnecessary code, creating buggy software, or even writing scripts to simulate computer activity.

Economists call this Goodhart’s law: when a measure becomes a target, it stops being a good measure. Uber saw a mild version of it after putting the number of code changes per engineer on an internal dashboard. According to Gergely Orosz’s Pragmatic Engineer newsletter, the volume of code barely moved, but engineers started splitting work into far more changes, so the load on the continuous integration servers, and their cost, went up.
Lines of code and commit counts are the oldest programming metrics, and they still have a narrow use. Change size helps explain why a review took long, and logged hours show where a team’s capacity went. Trouble starts when such a number is offered as evidence that someone got more productive.
Frameworks behind modern engineering metrics
Most software engineering metrics in use today come from four research-based frameworks. They overlap, and many teams borrow from more than one.
| Framework | Origin | What it covers | Typical metrics | Best for |
|---|---|---|---|---|
| DORA | Google’s DevOps Research and Assessment program, running since 2014 | Software delivery throughput and instability | Change lead time, deployment frequency, failed deployment recovery time, change fail rate, deployment rework rate | Judging the health of the delivery pipeline for one application or service |
| SPACE | GitHub and Microsoft Research, 2021 | Satisfaction and well-being, performance, activity, communication and collaboration, efficiency and flow | No fixed list: example metrics for each dimension, combined across several dimensions at once | A balanced view that includes how developers feel about their work |
| DevEx | Abi Noda, Margaret-Anne Storey, Nicole Forsgren, and Michaela Greiler, 2023 | Feedback loops, cognitive load, flow state | A survey measure and a system measure for each topic, such as build satisfaction and build time | Finding the friction developers hit in daily work |
| DX Core 4 | DX, 2024 | Speed, effectiveness, quality, business impact | Pull requests per engineer (read at team level), Developer Experience Index, change fail rate, share of time on new capabilities | One scorecard that pulls the other three together |
The official DORA guide lists the current five metrics and warns against using them as targets or comparing unlike applications. SPACE has no fixed formula, so its value lies in the dimensions it forces you to cover; our SPACE framework guide walks through each of them. In 2023, McKinsey proposed adding metrics of its own, such as contribution analysis, and engineers including Kent Beck criticized the idea, mostly because those metrics measure effort and output rather than outcomes.
The best developer productivity metrics
Below are 20 metrics for teams, grouped by what they reveal. Five of them are the DORA metrics; others draw on talks by Abi Noda, co-founder of the developer analytics company DX, and Roy Osherove, author of The Art of Unit Testing and Notes to a Software Team Leader. Each card lists what the metric measures, how to calculate it, what it helps you improve, and which metric to pair it with, so a gain in one place doesn’t hide a loss in another.
DORA throughput metrics
DORA’s current model has five metrics. Since 2024, it groups failed deployment recovery time with throughput, next to lead time and deployment frequency, and treats change fail rate and deployment rework rate as measures of instability.
1. Deployment frequency
What it measures: How often a team successfully releases to production.
How to calculate: Successful production deployments per day or per week, counted for each application or service
Impact potential: Shorten time to market and keep releases small enough to fix quickly
Pair with: Change fail rate. Twelve deployments a week with four rollbacks is a weaker result than six deployments with none, even though the first number looks better on a dashboard.
2. Change lead time
What it measures: How much time it takes a commit to get into production, including review, automated checks, approvals, and waiting
How to calculate: Median hours from commit to production deployment. Track the slowest 10% as well, because a steady median can hide changes stuck for days.
Impact potential: Get user feedback sooner and stop changes from piling up between releases
Pair with: Change fail rate, to make sure a shorter path to production doesn’t come from skipping review or tests
3. Failed deployment recovery time
What it measures: How long it takes to get service back after a deployment fails and someone has to step in right away. DORA replaced the older mean time to recovery with this metric in 2023, so it now counts only failures caused by a change, not outages from outside causes.
How to calculate: Median hours from a failed deployment to restored service. Review the longest cases one by one, since a single long incident often exposes a gap in ownership or rollback.
Impact potential: Shorten outages so users feel a failed release for minutes instead of hours
Pair with: Deployment rework rate, which shows how often recovery is needed in the first place
DORA instability metrics
4. Change fail rate
What it measures: The percentage of deployments that need immediate intervention, such as a rollback or a hotfix
How to calculate: Failed deployments divided by all deployments in the period, times 100. Agree on what counts as a failure before comparing months.
Impact potential: Increase customer satisfaction by reducing the number of outages
Pair with: Deployment frequency. Zero failures can simply mean almost no releases.
5. Deployment rework rate
What it measures: The share of deployments nobody planned, pushed out to fix an incident in production. DORA added it in 2024 to show how much delivery capacity goes to cleanup.
How to calculate: Unplanned deployments triggered by incidents divided by all deployments, times 100
Impact potential: Spot a team that merges more changes but spends a growing share of its time on hotfixes and reversals
Pair with: Change fail rate and investment balance
Code quality metrics
6. Escaped defect rate
What it measures: The share of bugs that reach production before anyone on the team catches them
How to calculate: Bugs found in production divided by all bugs found for the same releases, times 100. Weight them by severity so a typo doesn’t count like a data loss.
Impact potential: Check whether reviews and tests catch problems before users do
Pair with: Cycle time, because pressure to ship faster usually shows up here first
7. Rework rate (code churn)
What it measures: How much recently written code gets rewritten or deleted soon after it was merged
How to calculate: Lines changed in code younger than about three weeks divided by all lines changed in the period
Impact potential: Catch unclear requirements or rushed work weeks before they turn into bugs
Pair with: Pull request size. A burst of churn while a feature takes shape is expected, but churn that persists in the last days before a release deserves a closer look.
Test coverage, defect density, and technical debt ratio complete this group. They are most useful as trends, since hard targets on them invite gaming, and you’ll find them in the summary table below.
Code review metrics
8. Pull request size
What it measures: How much code a single pull request changes
How to calculate: Median lines added plus lines deleted per merged pull request
Impact potential: Get changes picked up sooner and reviewed more carefully; this is one of the earliest predictors of cycle time
Pair with: Escaped defect rate, to check that changes are smaller and still complete
9. Time to first review and review time
What it measures: How long a pull request waits before someone looks at it, and how long the review takes after that
How to calculate: Median business hours from review request to the first human comment, and from that comment to approval
Impact potential: Cut the waiting that makes up most of the cycle time and pushes developers into switching tasks
Pair with: Escaped defect rate. If an AI reviewer leaves comments automatically, exclude them from the count; otherwise the number improves while people take longer to review.
Flow and planning metrics
10. Cycle time
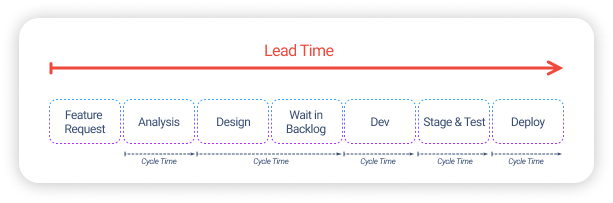
What it measures: How long a work item takes from the moment work starts until it is done, broken down by stage. Lead time covers a longer span, from the request to delivery, including the time an item waits in the backlog; here is how the two differ in more detail.
How to calculate: Median days from the moment an item moves into progress until it is done, split into coding, waiting for review, review, and waiting for deployment
Impact potential: Increase project planning accuracy and find the stage that slows work down the most
Pair with: Work in progress. Cycle time rarely improves while each developer juggles several open items.
11. Work in progress
What it measures: How many items are in progress at once and how long they have been open
How to calculate: Number of tasks in progress per developer or per team, plus the age of the oldest open item
Impact potential: Identify bottlenecks and sunk costs
Pair with: Cycle time. When items stay open for weeks, look for scope nobody pinned down or a reviewer with too much on their plate.
12. Velocity
What it measures: The amount of work that your team can accomplish in a given amount of time (sprint)
How to calculate: Story points or hours completed per sprint, averaged over at least three sprints (see how teams handle story point estimation)
Impact potential: Improve project and sprint planning
Pair with: Planning accuracy. Velocity is a planning measure, not a productivity score: points mean different things in different teams, and, as the Stack Overflow blog puts it, its accuracy evaporates once incentives are attached to it.
13. Planning accuracy
What it measures: The share of planned work a team actually delivers in a sprint or a quarter
How to calculate: Planned items completed divided by planned items, times 100
Impact potential: Make commitments to product, sales, and clients more reliable, and catch the planning fallacy at work early
Pair with: Scope added after sprint start. If accuracy is low because new work keeps arriving mid-sprint, the fix lies in intake and scope creep control.
Metrics that show where engineering time goes
These metrics come from time and task data. They show whether the team spends its hours on the work the business thinks it is paying for, which delivery metrics can’t tell you.
14. Investment balance
What it measures: How engineering hours split between new features, improvements to existing ones, maintenance, and unplanned work
How to calculate: Hours logged in each category divided by total hours for the period
Impact potential: Test the roadmap against reality. A plan that assumes 80% of capacity for features will keep slipping if maintenance and incidents take half the hours.
Pair with: Deployment rework rate, which often explains a rising share of unplanned work
15. Estimate vs. actual
What it measures: How far actual effort lands from the estimate for comparable work
How to calculate: Actual hours divided by estimated hours, tracked as a median ratio for each type of task
Impact potential: Base the next estimates on how long similar work really took, which makes it easier to keep projects on schedule from the first sprint
Pair with: Planning accuracy. Discuss large gaps as a team: estimates usually miss because of unknowns in the work, so the ratio is feedback on how the team estimates.
16. Focus time
What it measures: How much of the working week developers spend in uninterrupted blocks long enough for deep work
How to calculate: Hours in meeting-free blocks of two hours or more divided by working hours, taken from calendars, or a survey question about how many days a week developers get such a block
Impact potential: Give developers more time in a state of flow and fewer costly context switches
Pair with: Cycle time and meeting hours
The same time data supports two more metrics from the summary table: cost per feature (hours multiplied by each person’s cost rate) and weekly time lost to slow tools or waiting on others. McKinsey offers a reference point here: at top tech companies, the goal is to keep up to 70% of developer time in the inner loop of coding, building, and unit testing. Integration, release chores, and coordination make up the outer loop.
Developer experience metrics
Developer experience metrics capture how developers perceive their tools, processes, and working conditions. The DevEx framework sorts the friction developers meet into feedback loops, cognitive load, and flow state, and recommends measuring each with a survey and with system data, because neither tells the whole story. Survey answers and system data often disagree: a build that takes three minutes can still frustrate people who run it twenty times a day.
17. Developer experience score
What it measures: How developers rate the main sources of friction in their work
How to calculate: Share of favorable answers per question in a short quarterly survey, reported separately for each team and role, since a company-wide average hides problems in small groups
Impact potential: Surface problems that system data misses, such as flaky tests everyone reruns or a local setup that takes a day to get working, and spot burnout and attrition risks early
Pair with: A system metric on the same topic, for example build satisfaction with build time
Questions that tend to produce answers a team can act on:
- How easy or difficult is it to get a change into production?
- How often do you wait on builds, tests, or reviews long enough to switch to another task?
- How confident are you that our automated tests catch real problems?
- How easy is it to understand the code you work on most often?
- In a typical week, on how many days do you get at least two hours without meetings or interruptions?
- How clear is the link between your current work and the team’s goals?
Share what changed after each survey, or response rates will drop. Persistent low scores on workload and focus are also an early sign of developer burnout that a delivery dashboard won’t show. Onboarding speed, such as the time a new hire needs to merge their tenth pull request, and retention of strong engineers belong in this group too.
18. Team health
What it measures: Distribution of work among team members
How to calculate: Distribution of work items by type and quantity across team members
Impact potential: Create fair team workload distribution
Pair with: Developer experience score. An even split on paper can still hide one person who always gets the hardest or most tedious work, so managing workloads takes both numbers and conversation.
User and business outcome metrics
19. Customer satisfaction score
What it measures: How satisfied a customer is with your products or services
How to calculate: Surveys with scales and open questions
Impact potential: Improve customer relations and satisfaction
Pair with: Escaped defect rate, since quality problems are a common reason for a drop
20. Feature adoption
What it measures: Whether the people a feature was built for actually use it
How to calculate: Users who used the feature within 30 days of release divided by users it was meant for, times 100. Set the target before development starts, for example, that 40% of active accounts export at least one report in the first month.
Impact potential: Connect delivery to value and see which kinds of work pay off
Pair with: Cycle time, to see whether faster delivery goes into work people use


DORA benchmarks: what good delivery looks like
DORA groups survey respondents into performance clusters every year. DORA’s 2024 State of DevOps report is the latest edition with these four levels:
| Level | Change lead time | Deployment frequency | Change fail rate | Failed deployment recovery time | Share of respondents |
|---|---|---|---|---|---|
| Elite | Less than one day | On demand, several deploys per day | 5% | Less than one hour | 19% |
| High | One day to one week | Once a day to once a week | 20% | Less than one day | 22% |
| Medium | One week to one month | Once a week to once a month | 10% | Less than one day | 35% |
| Low | One to six months | Once a month to once every six months | 40% | One week to one month | 25% |
The medium cluster fails less often than the high one: DORA chose to call the faster teams high performers, and says the better trade-off depends on the application and what its users expect. The report also stresses that improving matters more than reaching a level, since the best teams are those that achieve elite improvement rather than elite performance. The clusters use the original four metrics, and the 2025 edition replaced them with seven team profiles, so compare a team with its own history first and with these levels second.
Performance metrics for individual developers
Most metrics in this guide describe a system, and applying them to one person is unfair. A developer’s deployment frequency depends on reviewers, the build pipeline, and the release process, none of which they control alone. Individual output numbers also miss the people who make everyone else faster, such as the senior engineer who unblocks three teammates a day or the developer who quietly refactors and tests so others can ship features sooner.
Fair software developer performance metrics start from what the role is expected to deliver, with activity data used only to explain a miss. Laura Tacho describes this approach in detail in her post on evidence for individual performance, and the table below follows the same logic.
| Role level | Fair evidence | Avoid as a score |
|---|---|---|
| Junior developer | Delivery of agreed tasks, growing independence on more complex tasks, how review feedback changes over time | Lines of code, commit counts, comparison with seniors |
| Mid-level developer | Features delivered within about a week of their own forecast, rollbacks and escaped defects in their changes, review participation | Story points per person, number of pull requests |
| Senior or staff engineer | Architecture decisions and their results, the quality of work by people they mentor, feedback from peers and cross-functional partners | Personal commit history |
| Tech lead or engineering manager | Team-level metrics they are responsible for improving, such as cycle time, change fail rate, or the developer experience score | Rankings of the individual numbers of their reports |
Even the fair software engineer performance metrics above are inputs to a conversation with the developer. How to gather that evidence and run reviews around it is a separate topic, and our guide to measuring developer productivity covers it step by step.
All metrics at a glance
The table lists the 20 metrics above plus second-tier signals, such as flow efficiency, weekly time loss, and other developer efficiency metrics, that help in specific situations. It doubles as a list of software development metrics examples, with a formula and a data source for each.
| Metric | Group | How to calculate | Data source | Level | Pair with |
|---|---|---|---|---|---|
| Deployment frequency | DORA throughput | Successful deployments per day or week | CI/CD pipeline | Team, service | Change fail rate |
| Change lead time | DORA throughput | Median time from commit to production | Version control, CI/CD | Team, service | Change fail rate |
| Failed deployment recovery time | DORA throughput | Median time from failed deployment to recovery | Incident tracker | Team, service | Deployment rework rate |
| Change fail rate | DORA instability | Failed deployments / all deployments | CI/CD, incident tracker | Team, service | Deployment frequency |
| Deployment rework rate | DORA instability | Incident-driven deployments / all deployments | CI/CD, incident tracker | Team, service | Investment balance |
| Escaped defect rate | Code quality | Production bugs / all bugs for the same releases | Issue tracker | Team | Cycle time |
| Rework rate | Code quality | Changes to code under three weeks old / all changes | Version control | Team | Pull request size |
| Test coverage | Code quality | Share of code run by automated tests (watch the trend) | Test tooling | Codebase | Change fail rate |
| Defect density | Code quality | Bugs per thousand lines or per feature | Issue tracker, version control | Codebase | Escaped defect rate |
| Technical debt ratio | Code quality | Estimated cost to fix known issues / cost to build | Static analysis | Codebase | Investment balance |
| Pull request size | Code review | Median lines changed per merged pull request | Version control | Team | Escaped defect rate |
| Time to first review, review time | Code review | Median hours to first human comment and to approval | Version control | Team | Escaped defect rate |
| Cycle time | Flow and planning | Median days from start to done, by stage | Issue tracker | Team | Work in progress |
| Flow efficiency | Flow and planning | Active work time / total cycle time | Issue tracker | Team | Work in progress |
| Work in progress | Flow and planning | Open items per developer, age of the oldest | Issue tracker | Team | Cycle time |
| Velocity | Flow and planning | Points or hours completed per sprint | Issue tracker | Team | Planning accuracy |
| Planning accuracy | Flow and planning | Planned items done / planned items | Issue tracker | Team | Scope added after sprint start |
| Scope added after sprint start | Flow and planning | Items or points added mid-sprint / planned | Issue tracker | Team | Planning accuracy |
| Sprint burndown | Flow and planning | Remaining work against days left in the sprint | Issue tracker | Team | Scope added after sprint start |
| Investment balance | Engineering time | Hours by category / total hours | Time tracking | Team, organization | Deployment rework rate |
| Estimate vs. actual | Engineering time | Actual hours / estimated hours, by task type | Time tracking, issue tracker | Team | Planning accuracy |
| Focus time | Engineering time | Hours in two-hour meeting-free blocks / working hours | Calendars, survey | Team | Cycle time |
| Cost per feature | Engineering time | Hours on the feature times each person’s cost rate | Time tracking | Organization | Feature adoption |
| Weekly time loss | Engineering time | Share of the week lost to obstacles, by survey | Survey | Team, organization | Developer experience score |
| Developer experience score | Developer experience | Favorable answers per survey question | Survey | Team | Matching system metric |
| Time to 10th pull request | Developer experience | Days from start date to a new hire’s tenth merged pull request | Version control, HR data | Team | Onboarding survey |
| Retention of engineers | Developer experience | Engineers who stayed / engineers at the start of the year | HR data | Organization | Developer experience score |
| Customer satisfaction score | Outcome | Share of satisfied respondents | Customer surveys | Product | Escaped defect rate |
| Feature adoption | Outcome | Users of the feature / users it was built for | Product analytics | Product | Cycle time |
| Team health | Developer experience | Spread of work items by type and person | Issue tracker, time tracking | Team | Developer experience score |
Which metrics to start with
Start with a problem the team already feels and pick the metrics that explain it. Each row below names a common symptom, the two or three developer metrics that show its cause, and where to look next.
| If the problem is | Start with | Then look at |
|---|---|---|
| Releases keep slipping | Planning accuracy, scope added after sprint start | Estimate vs. actual, investment balance |
| Everyone is busy, but work moves slowly | Work in progress, cycle time by stage | Time to first review, pull request size |
| Too many incidents after releases | Change fail rate, escaped defect rate | Deployment rework rate, test coverage trend |
| The roadmap never gets enough attention | Investment balance | Deployment rework rate, technical debt ratio |
| People are tired or leaving | Developer experience score, focus time | Team health, retention of engineers |
| New hires take months to contribute | Time to 10th pull request | Survey questions on documentation and code clarity |
| Leadership asks whether AI tools pay off | Change lead time and change fail rate before and after adoption | The AI-specific metrics in the section below |
Once the cause is clear, the fixes themselves are a separate job; our guide to improving developer productivity covers the most common ones.
How to combine metrics into a scorecard
The good news is that we can maximize the accuracy of the metrics. Steve McConnell developed a list of attributes for identifying reliable performance metrics. More than that, he evaluated the most commonly used team-level developer performance measurements according to them:
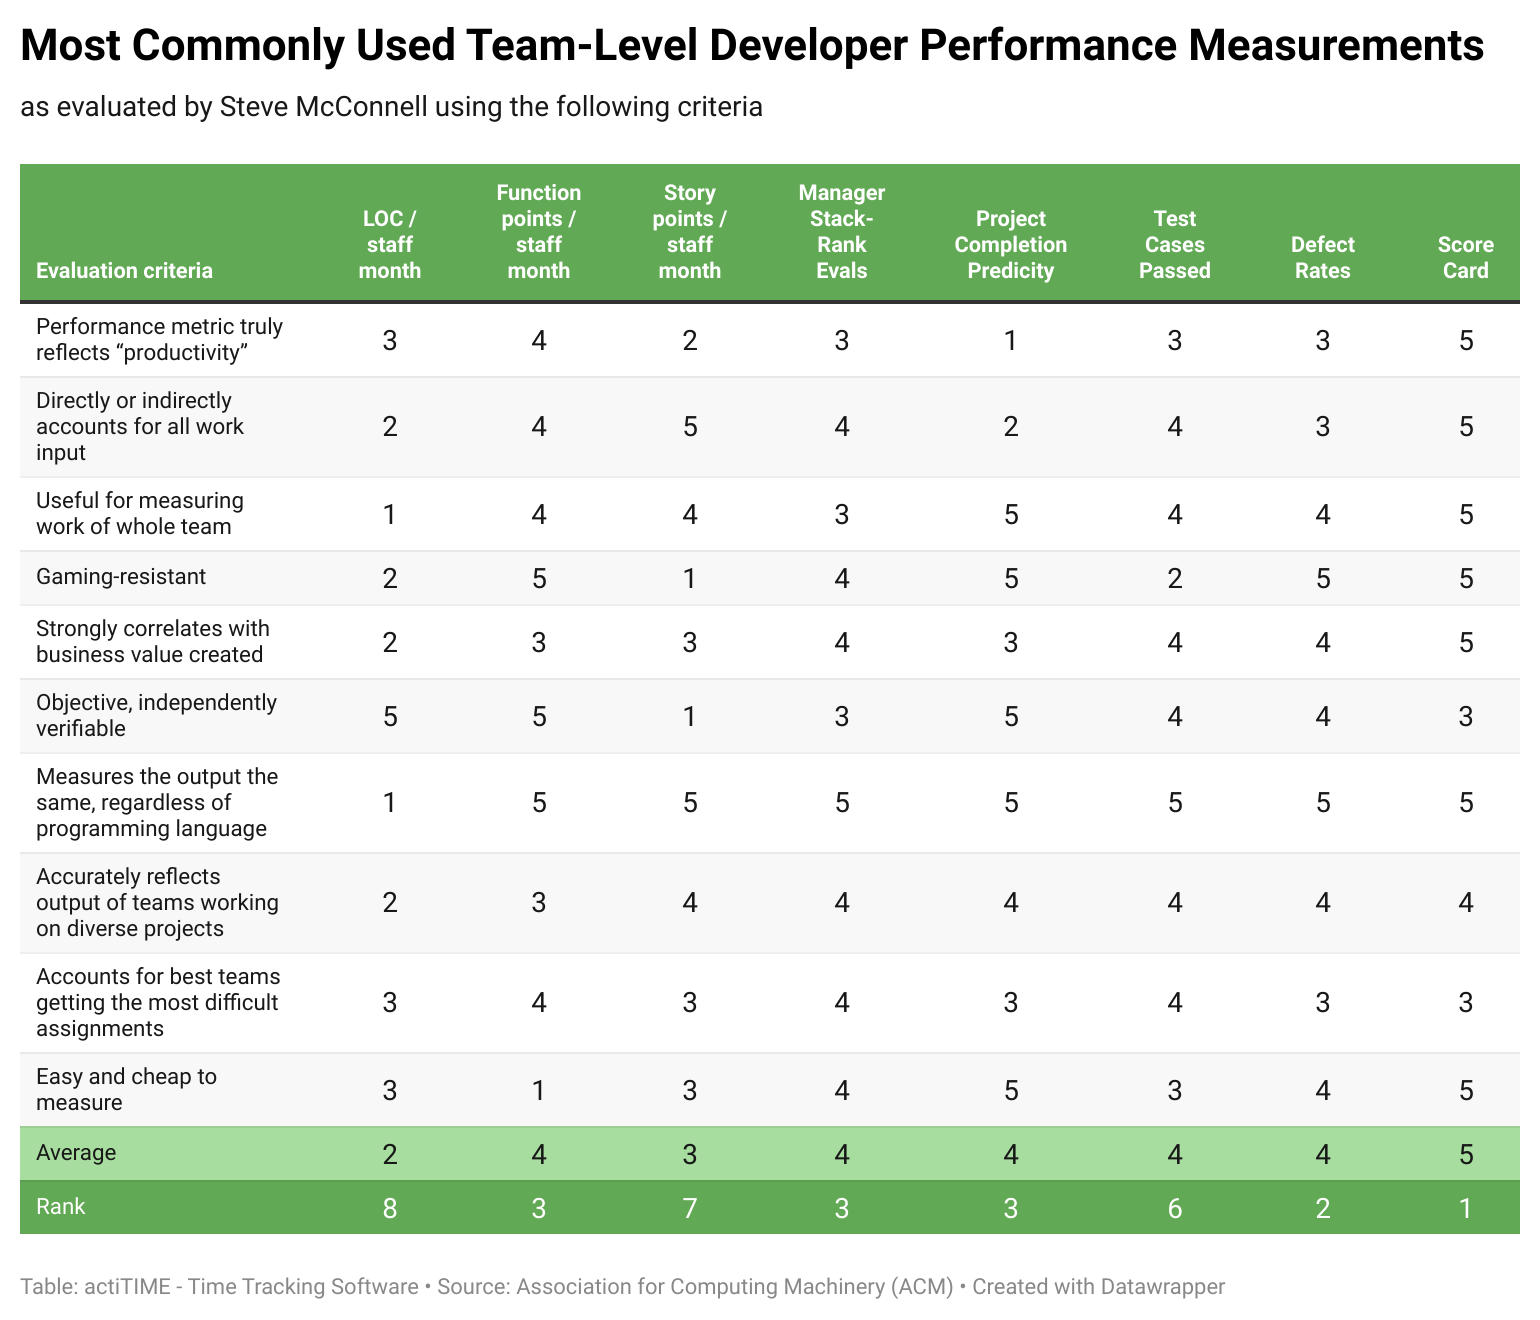
McConnell scored eight common measurements from 1 to 5 against ten criteria, including whether a metric reflects productivity, accounts for all work input, resists gaming, tracks business value, and is cheap to collect. The scorecard ranked first, defect rates second, and lines of code per staff month last, just below story points per staff month.
So, the leading measurement is a scorecard: it contains a set of developer performance metrics, which makes it far more reliable than any single number. If you include metrics that account for work input of the whole team and reflect the acquired business value, your scorecard will give the most balanced view and keep the effect of the 10x individual variation small.
A few rules keep a scorecard useful:
- Start with three to five metrics tied to one problem, and add more only when the first set is used in real decisions.
- Pair every speed metric with a stability or quality metric, so one can’t improve at the other’s expense.
- Mix leading and lagging indicators. Pull request size, time to first review, and work in progress move weeks before lead time and change fail rate do.
- Separate metrics for teams from metrics about teams. Engineering leader Lena Reinhard draws this line: the first kind is owned by the team and discussed in retrospectives, the second is aggregated for leadership. Mixing them up breeds cynicism and gaming.
- Match the review rhythm to the metric. Look at improvement metrics weekly and at diagnostic ones, such as the DORA metrics, monthly or quarterly.
Here is how this works for a product team of six developers whose releases slip and whose sprints keep getting eaten by hotfixes:
| Metric | Type | Baseline | Target next quarter | Counter-metric |
|---|---|---|---|---|
| Planning accuracy | Lagging | 58% | 75% | Scope added after sprint start (now 22%) |
| Unplanned work share | Lagging | 31% of logged hours | Under 20% | Deployment rework rate |
| Change fail rate | Lagging | 16% | Under 10% | Deployment frequency (keep at three or more a week) |
| Time to first review | Leading | 26 business hours | Under 8 business hours | Escaped defect rate |
| Work in progress per developer | Leading | 3.4 items | 2 or fewer | Cycle time (median 6.5 days) |
The logic runs backward from the symptom. Broken releases create hotfixes, hotfixes become unplanned work, and unplanned work wrecks the sprint plan, so the team works on stability and flow first and expects planning accuracy to follow. If change fail rate drops but planning accuracy doesn’t move, the next suspect is scope arriving mid-sprint.
The right emphasis also changes with the company’s stage:
- Startup: deployment frequency and lead time come first, and a higher fail rate is an accepted price for faster feedback.
- Growing company: review queues and slow onboarding start to hurt, so code review and planning metrics move up the list.
- Enterprise or regulated industry: change fail rate and recovery time lead, longer lead times are expected because of compliance checks, and comparing a team with its own past says more than outside benchmarks.
Metrics for teams using AI coding tools
Coding assistants and agents widen the gap between activity and value. Counting prompts, tokens, accepted suggestions, or generated lines tells you how heavily a tool is used; it says nothing about whether the change it produced was worth shipping, got a proper review, or was ready to release.
In DORA’s 2024 report, every 25% increase in AI adoption came with an estimated 1.5% drop in delivery throughput and a 7.2% drop in delivery stability. The 2025 report found that 90% of respondents now use AI and linked adoption to higher throughput, while instability kept rising. It described AI as an amplifier: it strengthens well-organized teams and exposes weaknesses in fragmented ones.
Alongside the core metrics above, teams adopting AI tools track a few specific ones:
- Change fail rate and escaped defects for changes written with AI help, compared with the team’s other changes
- Change lead time for comparable tasks before and after the rollout, so a speedup in the editor isn’t mistaken for a speedup in delivery
- Reviewer load: hours of review per merged change and the length of the review queue
- How much merged work involved AI, with suggestions a developer accepted counted apart from pull requests an agent opened on its own
- For pull requests opened by agents: how many get merged and how much a person had to change first
- Spend on AI tools per merged change, watched as a trend over a quarter or two
When the tools save time in the editor and lead time doesn’t budge, look at what happens after the code is written. A review queue or a manual release step usually absorbs the gain, and that becomes the next thing to fix.
How actiTIME supports time-based developer metrics
Measuring developer performance is not easy: you need to track project management metrics, calculate business costs and profits, and rely on time metrics to plan your projects with maximum accuracy. You can do most of these things in time and project management systems.
For example, actiTIME provides a time and project management system where you can manage workloads, review project progress, see business costs and profits, and more.
Build custom workflows, assign tasks to your team members, and see how time and money costs are distributed across tasks, project stages, projects, and clients.
That data feeds several of the metrics in this guide directly:
- Investment balance and unplanned work share: log time against types of work or task categories, such as new features, maintenance, and incidents, and see the split for any team and period.
- Estimate vs. actual: set time estimates on tasks and compare them with tracked hours in the estimated vs. actual time report.
- Cost per feature: apply each person’s cost rate to the hours spent and get the cost of work for a task, a project stage, or a whole project.
- Team health: review how work and hours are distributed across the team before someone is overloaded.
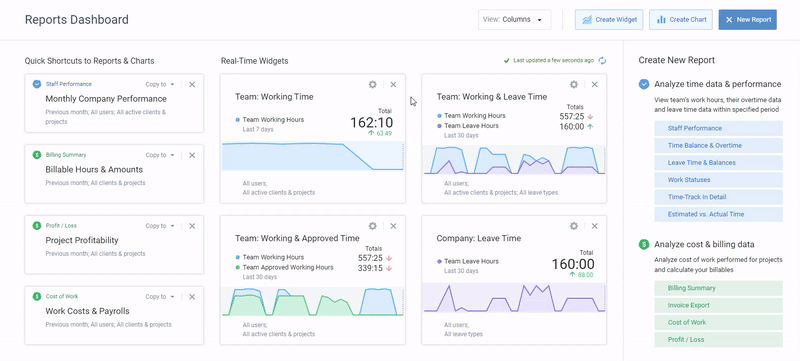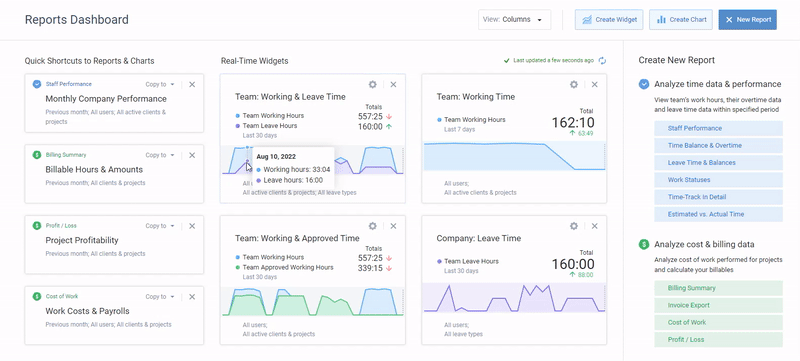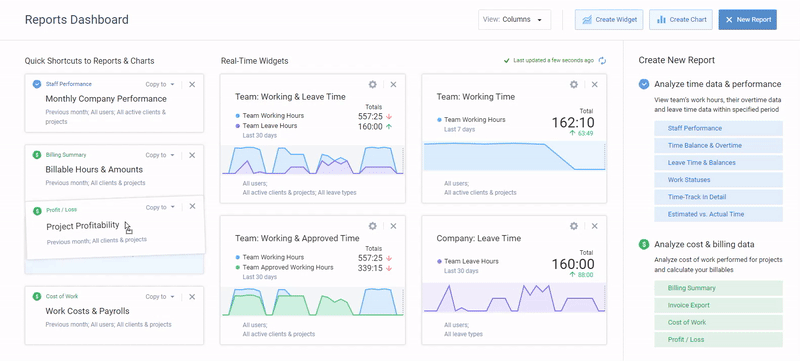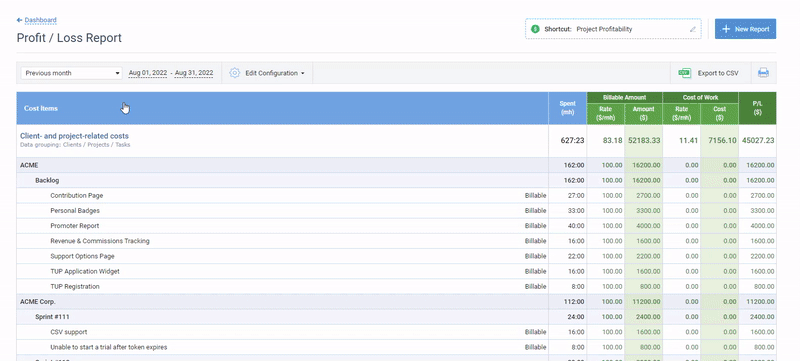
Reports dashboard in actiTIME – set up real-time data widgets
and add report shortcuts for quick access
Set up deadlines, time estimates, time or cost budgets. Create custom fields for tasks to upgrade your time, cost, and performance reports and see how similar items perform.
Developers can log time in the web timesheet, the mobile app, or the free Chrome extension, which tracks time spent in online tools automatically and syncs it to timesheets. Zapier connects actiTIME with more than 2,000 apps, and the API supports custom reports and data exchange with your own systems. If you’re still choosing a tool, our list of developer time tracking software compares the main options.
The quickest way to see your own numbers is a free 30-day trial: every feature is available, and no credit card is needed. After it ends, teams of one to three users can stay on the free version, while larger teams pay $6 per user per month for 1–40 users or $5 per user per month for 41–200 users, billed annually.
FAQ
What is the difference between developer productivity and developer performance?
Productivity describes how efficiently a team or a system turns engineering time into working software, so it is mostly measured at team level with delivery and flow metrics. Performance describes how well a person meets the expectations of their role, including things no dashboard captures, such as mentoring and design judgment. The two overlap, but treating a team productivity number as someone’s performance score is the most common way metrics go wrong.
Are DORA metrics enough to measure developer productivity?
No. DORA metrics describe how well software moves from commit to production and how stable it is once there, which makes them a strong baseline for delivery health. They say nothing about whether the team builds the right things, how much time goes to unplanned work, or whether developers can sustain the pace. Add at least one developer experience measure and one outcome measure, such as feature adoption, to get a fuller picture.
Should developers see the metrics collected about their work?
Yes. Hidden metrics breed suspicion, and teams can’t improve numbers they never see. Share team-level dashboards with the whole team, explain what each metric is for, and involve developers in choosing them. Keep anything that touches a single person private between that person and their manager, and anonymize survey results, because personal circumstances, such as a health issue or caring duties, are nobody else’s business.
Which metric should a team track first if it measures nothing today?
Cycle time, broken down by stage, is the most useful single starting point. It needs only issue tracker or version control data, and looking at where items wait, in review or before deployment, quickly points to the biggest bottleneck. Add change fail rate next so that any speed gained doesn’t come at the cost of stability.
Can a small team measure productivity without a dedicated analytics platform?
Yes. Deployment frequency, lead time, and pull request size can be pulled from the APIs of your Git host and CI system, cycle time and work in progress from issue tracker exports, and investment balance or estimate vs. actual from a time tracking tool. A spreadsheet updated weekly is enough to start. Dedicated platforms start to pay off when several teams and repositories need the same definitions and automatic updates.